User reference / Read the reports
Runs & prompt library
Find experiments, compare configurations and browse the execution history of one challenge.
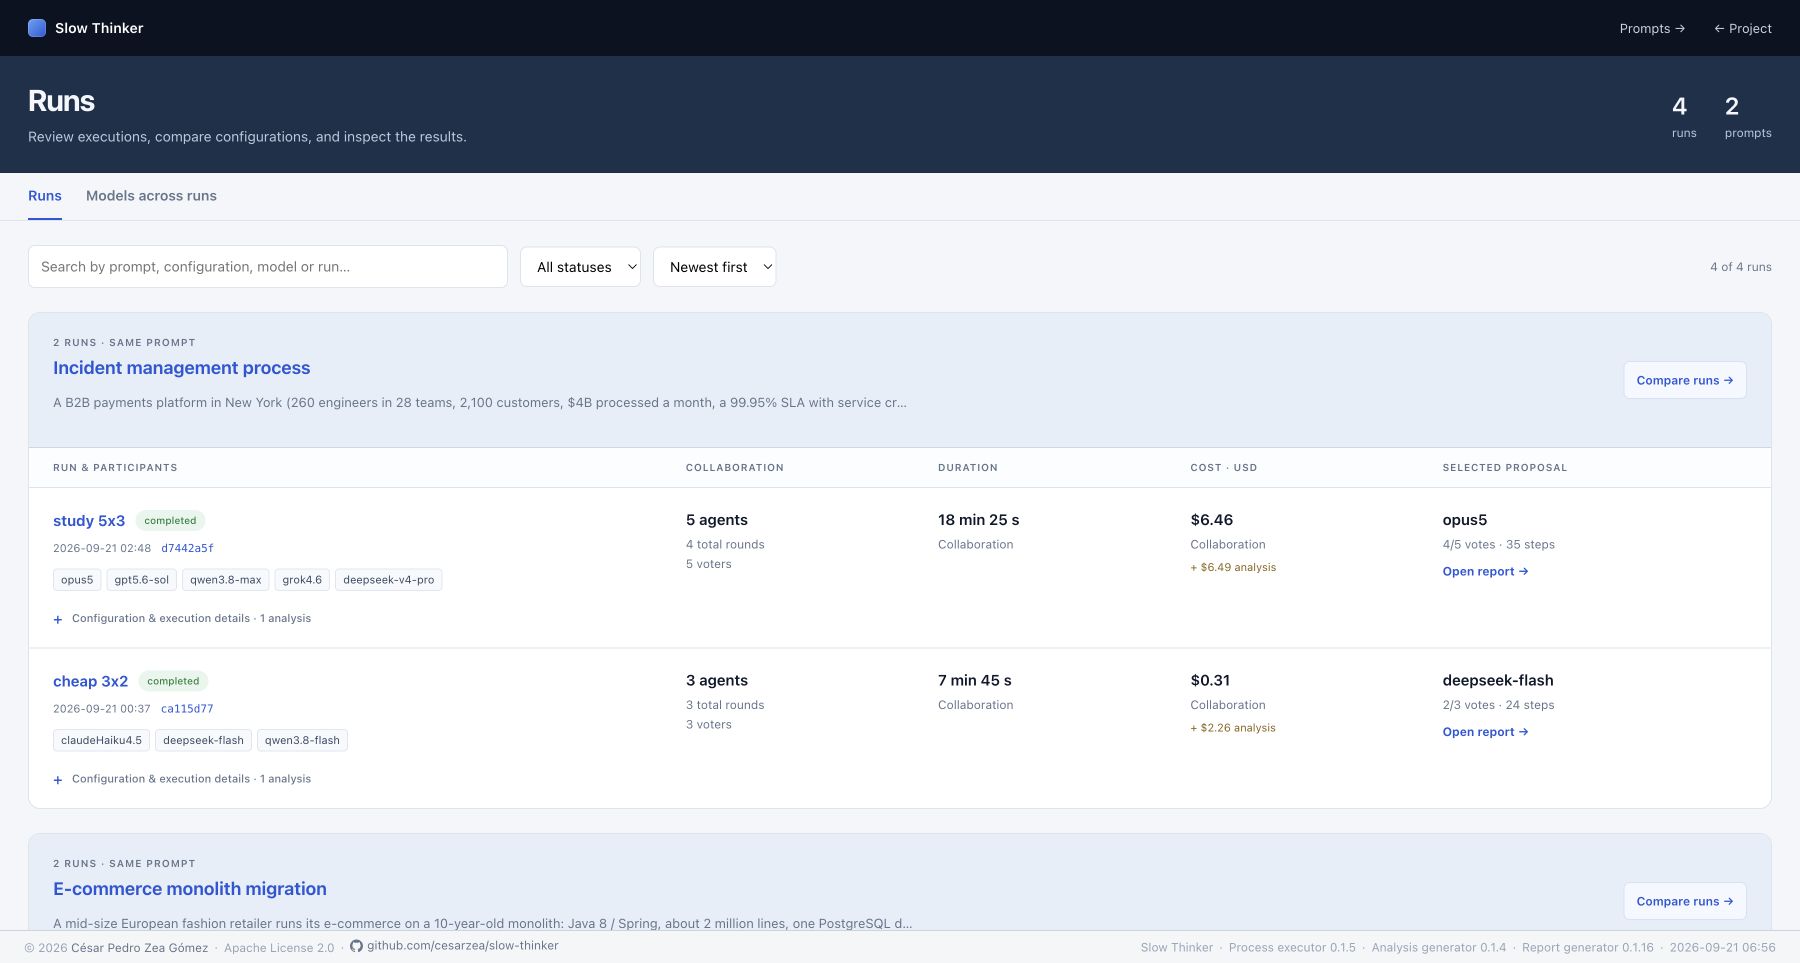
The run index groups executions by prompt identity. The fixed header, hero, view tabs and footer stay in place while the content scrolls. Counts at the top describe the whole library; the toolbar count describes the current filter.
Report 0.1.16
Captured 2026-09-21 · Capture provenanceExplore this view ↗
| Element | Meaning and interaction |
|---|---|
| Runs / prompts totalsReviewed R 0.1.16 | Number of recorded executions and prompt groups in this index. The prompt total excludes unexecuted catalogue cases. |
| Runs tabReviewed R 0.1.16 | The grouped execution list. Returning from the model view restores its previous scroll position. |
| Search runsReviewed R 0.1.16 | Case-insensitive substring search over prompt, title, label, task UUID, configuration key, models and selected agent. It is not a semantic search. |
| StatusReviewed R 0.1.16 | Restrict to one of the recorded status values. “Completed” means collaboration completed, not a validated solution. |
| Newest / oldest firstReviewed R 0.1.16 | Sort executions within each prompt group. Prompt groups remain together. |
| “x of y runs” / empty messageReviewed R 0.1.16 | Visible matches against total entries. Empty prompt groups disappear while filtering. |
| Group headerReviewed R 0.1.16 | Prompt title, statement preview and number of runs sharing the key. Title and “Compare runs” open its history. |
| Run name, status and dateReviewed R 0.1.16 | Configuration label or “Unnamed run”, saved task status and start time. Both name and short UUID open the report. |
| Model chipsReviewed R 0.1.16 | Recorded participants; the expanded details reveal full provider/model and reasoning settings. |
| CollaborationReviewed R 0.1.16 | Valid initial proposals, total recorded round range including round 0, and valid saved voters. These can differ from configured counts after failures. |
| DurationReviewed R 0.1.16 | Task updated_at − created_at, formatted for display. It is collaboration elapsed time, not summed model time or analysis duration. |
| Cost · USDReviewed R 0.1.16 | Estimated cost of stored proposal and vote calls. The separate + analysis amount is for the latest assessment only. “Unknown” means a complete estimate is unavailable. |
| Selected proposalReviewed R 0.1.16 | Winner's model/name, votes received out of valid votes and number of steps. “None yet” if no plan exists. |
| Open reportReviewed R 0.1.16 | Opens that run's report.html, which uses its latest saved analysis. |
| Configuration & execution detailsReviewed R 0.1.16 | Expand a row to see full models/settings, run ID, configuration ID, executor/package provenance, initial-plus-refinement breakdown, collaboration tokens, latest analysis tokens where recorded, and selected agent. The summary counts all saved analyses. |
Report 0.1.16
Captured 2026-09-21 · Capture provenanceExplore this view ↗
| Column or control | What it counts |
|---|---|
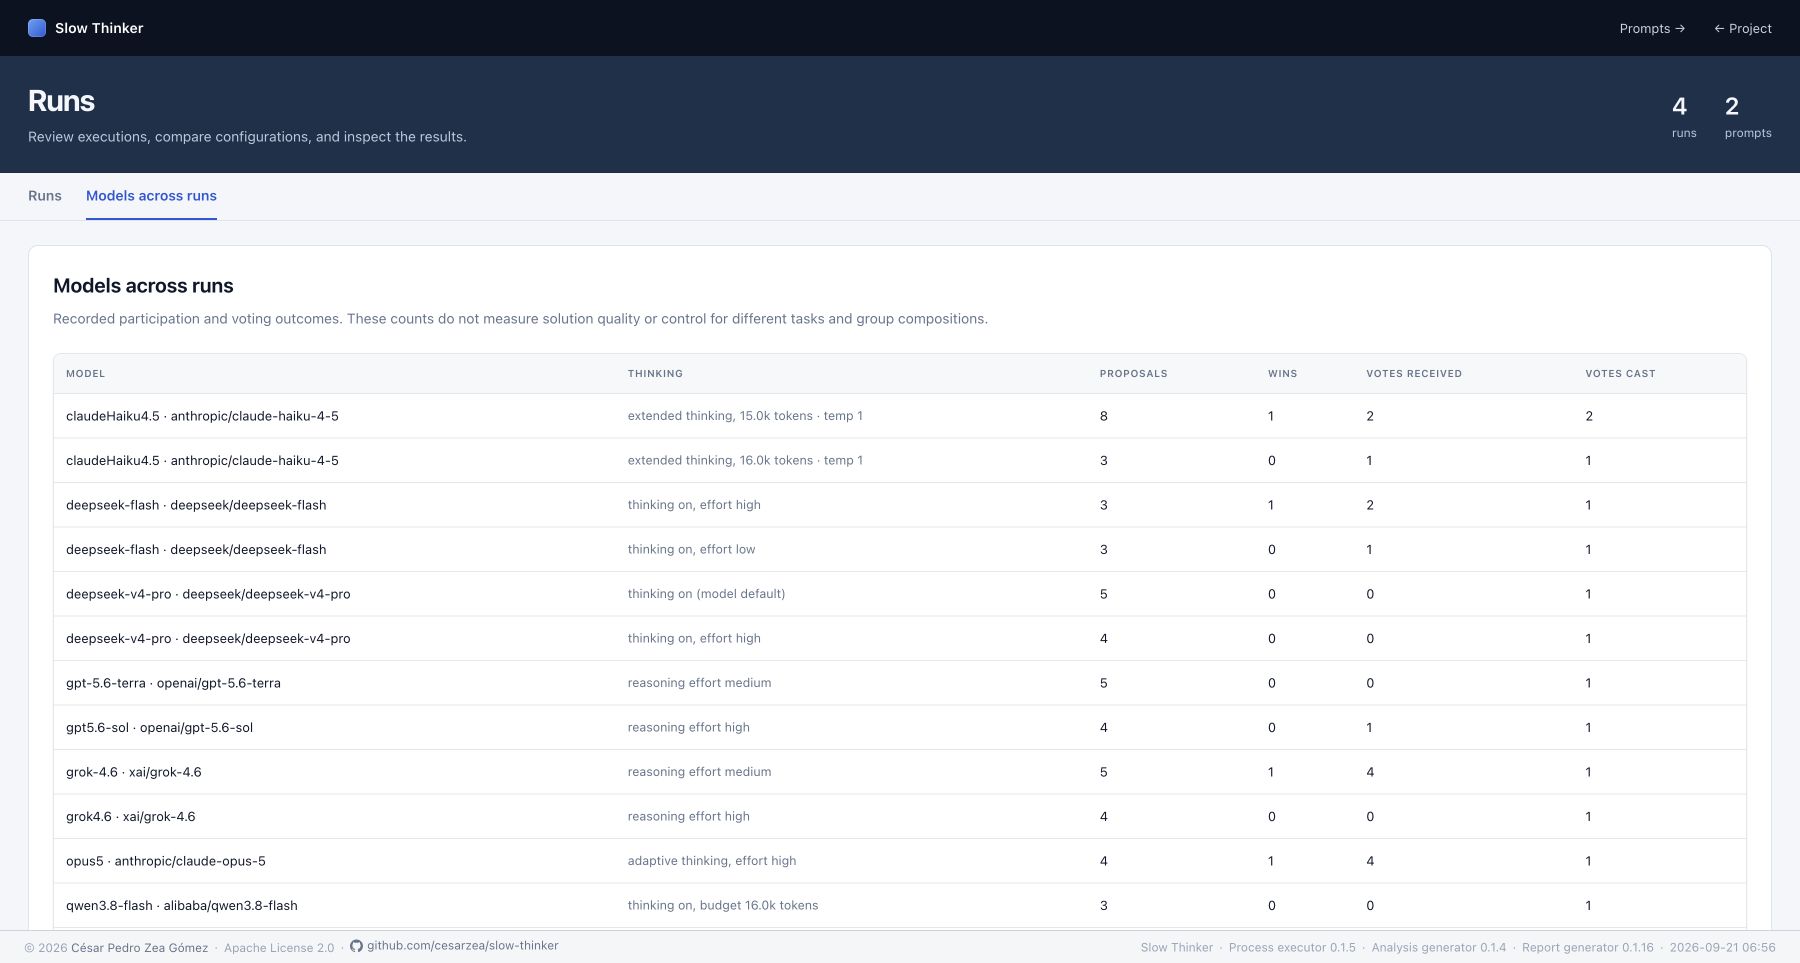
| Models across runs tabReviewed R 0.1.16 | Aggregates the library's loaded runs. The Runs tab's search/status filters do not filter this table. |
| Model / ThinkingReviewed R 0.1.16 | Groups by the displayed model label and effective-settings text. Different names or settings may form separate rows. |
| ProposalsReviewed R 0.1.16 | All saved proposals from all rounds by that group. It is not the number of independent experiments. |
| WinsReviewed R 0.1.16 | Runs whose selected proposal was written by that model/settings group, including a fallback selection if one occurred. |
| Votes receivedReviewed R 0.1.16 | Valid saved votes targeting proposals written by that group. |
| Votes castReviewed R 0.1.16 | Valid saved votes submitted by that group. |
These are participation and voting counts. Task difficulty, council composition, round count and repeated participation are not controlled. They do not form a model-quality benchmark. The two view tabs support Left/Right arrows and Home/End when focused.
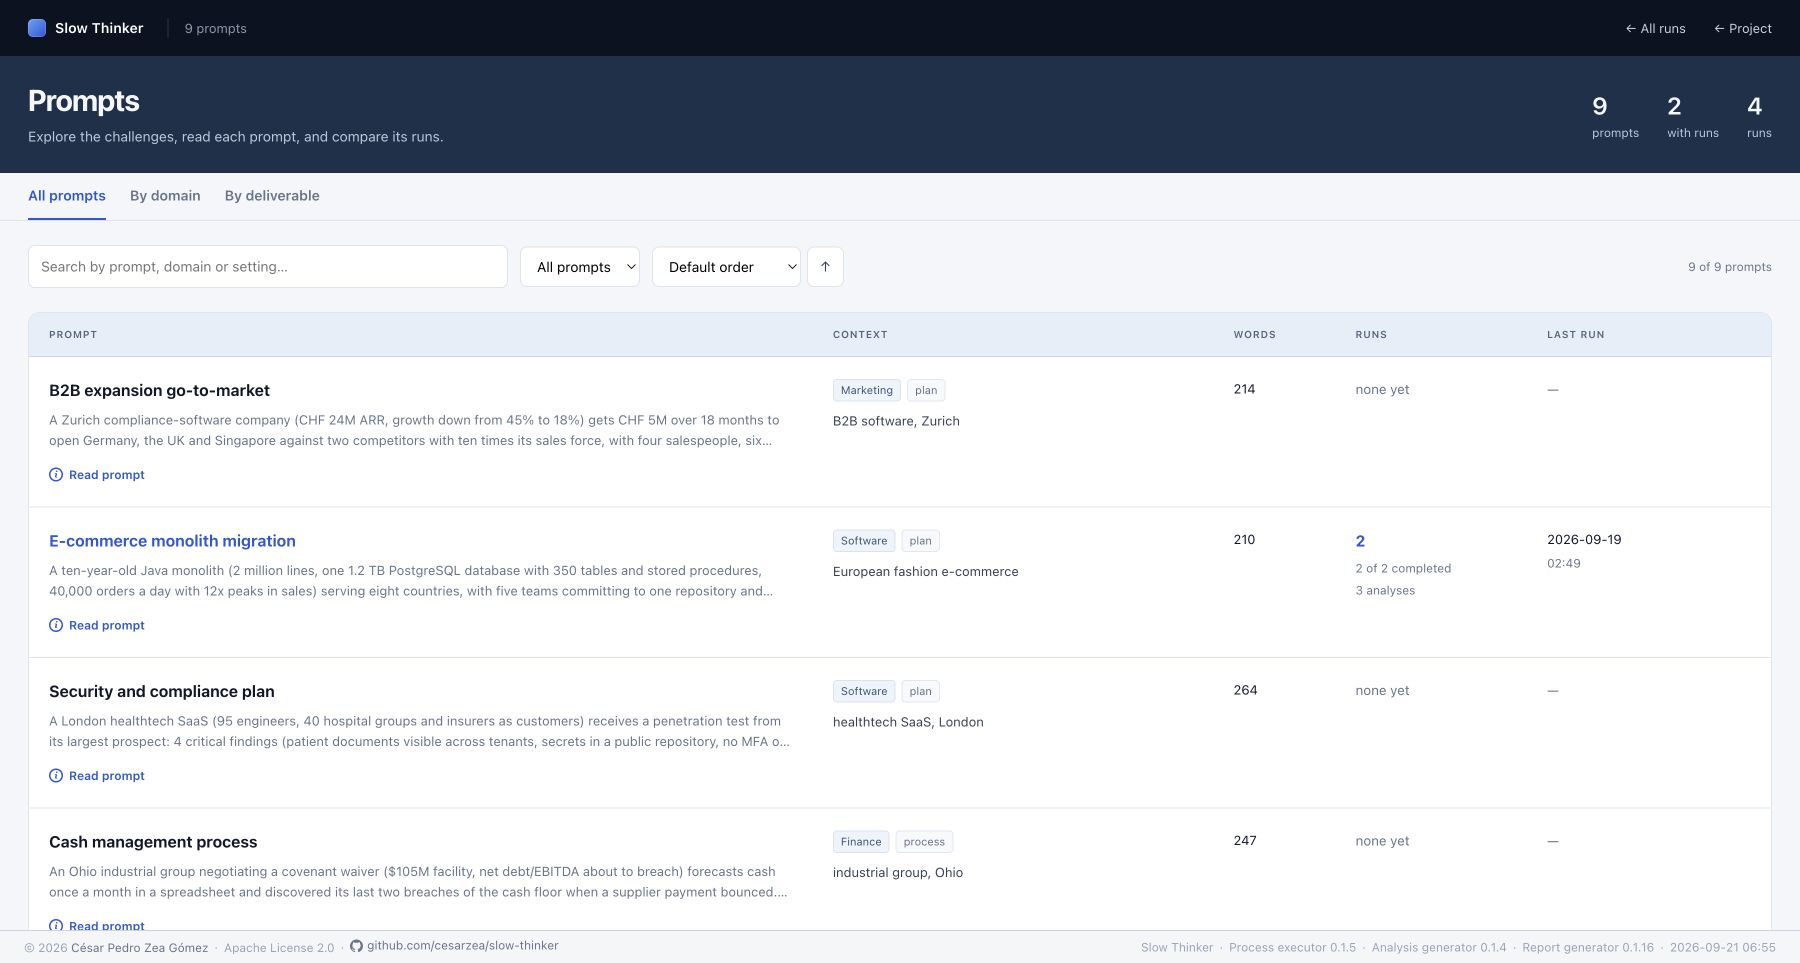
The prompt catalogue combines JSON task files from the examples directory with prompts found in recorded runs. Cases without executions are still readable.
Report 0.1.16
Captured 2026-09-21 · Capture provenanceExplore this view ↗
| Element | Meaning and interaction |
|---|---|
| Prompts / with runs / runsReviewed R 0.1.16 | Total catalogue entries, entries with at least one execution, and the sum of their executions. |
| All prompts / By domain / By deliverableReviewed R 0.1.16 | Choose a flat list or grouped sections. Group headers show the classification and visible prompt count; unspecified values are grouped separately. |
| Search promptsReviewed R 0.1.16 | Substring search across title, domain, deliverable, setting, key, filename and full prompt text. |
| Run statusReviewed R 0.1.16 | Show all, with runs, or not yet run. This is presence of an execution, not successful completion. |
| Sort promptsReviewed R 0.1.16 | Default order, name, domain, deliverable, setting, word count, run count, completed runs, analysis count or last run. |
| Direction arrowReviewed R 0.1.16 | Reverse the selected ordering. Disabled in default order. Numeric dropdown sorts and last-run sort initially use descending order; text sorts use ascending order. |
| Clickable column headersReviewed R 0.1.16 | Prompt sorts by title, Context by domain, Words by word count, Runs by run count, Last run by date. Clicking the same header reverses direction. |
| Prompt title and summaryReviewed R 0.1.16 | about.title and about.summary, with filename/prompt fallbacks. Executed prompts link to their history. |
| Read promptReviewed R 0.1.16 | Opens the full statement in a dialog, including content key, filename if available and saved input elements if present. Close with ×, Escape or the backdrop; focus returns to the opener. |
| ContextReviewed R 0.1.16 | Domain badge, deliverable badge and setting from about metadata. Unspecified values show a fallback. |
| WordsReviewed R 0.1.16 | len(prompt.split()): whitespace-separated words in the task statement. This is not a token count. |
| RunsReviewed R 0.1.16 | Executions, completed executions and total saved analyses for that prompt. “None yet” means no execution, not an error. |
| Last runReviewed R 0.1.16 | Latest task start date/time, or a dash if none exists. |
| Results count / empty stateReviewed R 0.1.16 | Visible prompts out of catalogue size; no-match message when all are filtered out. |
Report 0.1.16
Captured 2026-09-21 · Capture provenanceExplore this view ↗
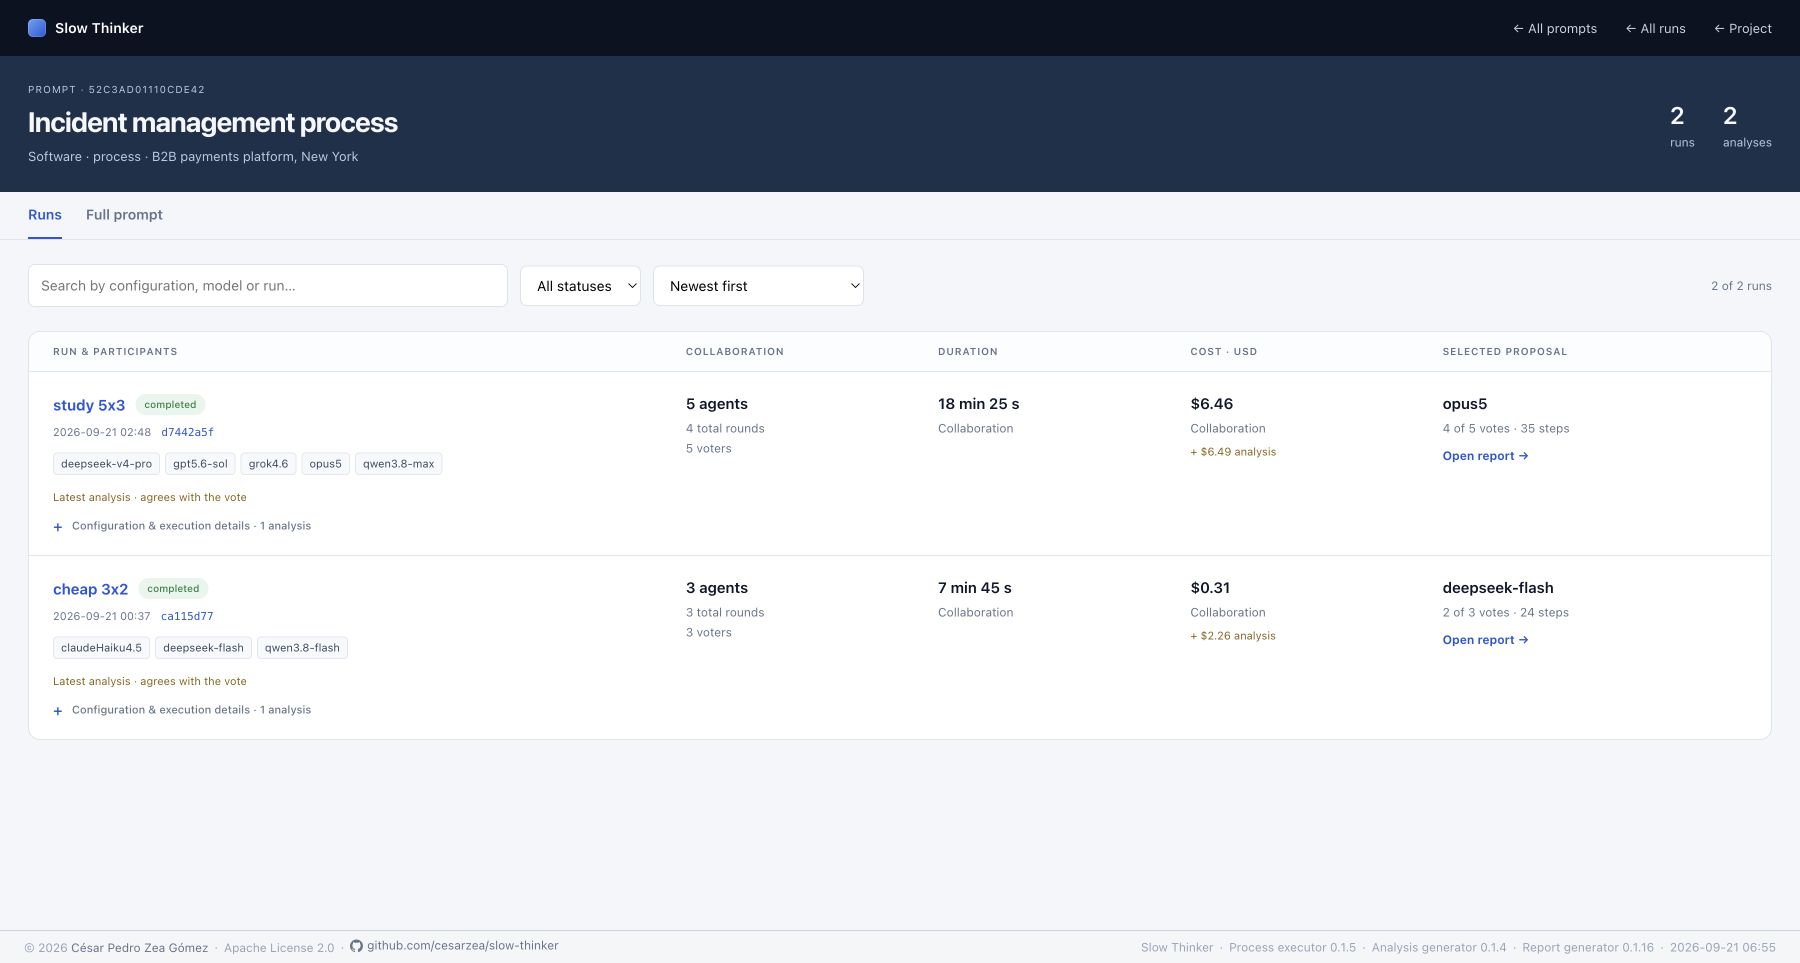
The prompt history keeps one row per run so it can grow without adding a column for every experiment. The shared title, content key and domain/deliverable/setting appear above the rows.
| Element | Meaning and interaction |
|---|---|
| Runs / analyses totalsReviewed R 0.1.16 | All executions for the key and the sum of their saved assessments. An analysis is not another execution. |
| Runs / Full prompt tabsReviewed R 0.1.16 | Switch between execution history and the exact shared statement, key, source filename if available and input elements. |
| Search, status and date sortingReviewed R 0.1.16 | As in the run index, restricted to this prompt. Search covers run/configuration identity, models and winner. |
| Lowest collaboration costReviewed R 0.1.16 | Sort by proposal-plus-vote estimate; unknown costs go last. It does not rank analysis expense or quality. |
| Run summary rowReviewed R 0.1.16 | Same identity, participant, collaboration, duration, cost and winner fields as the index. |
| Latest analysis signalReviewed R 0.1.16 | “Agrees/disagrees with the vote” when a compatible blind assessment contains a vote comparison. |
| Expanded model and execution detailsReviewed R 0.1.16 | Full model/settings list, run and configuration IDs, executor version, round breakdown and collaboration tokens. |
| Selected proposal detailsReviewed R 0.1.16 | Selected agent, valid vote count, step count, displayed graph dependencies plus redundant dependencies, largest contributor by title matching, and number of legacy agent notes. |
| Largest contribution by title matchingReviewed R 0.1.16 | Highest number of selected-plan steps attributed to one agent's original introductions. Ties use copied count then agent number. This can differ from the winner. |
| Latest analysis detailsReviewed R 0.1.16 | Analyst/model/settings, convergence judgment per refinement, blind first choice, agreement with vote, improvement over every initial proposal, and that assessment's cost. Missing values show “Not available” or “Not analysed”. |
| All prompts / All runsReviewed R 0.1.16 | Return to the catalogue or full execution library. |
Analysis details summarize the latest record. Open the run's About tab for its full analysis history. Historical assessments are not summed into the row's analysis cost.
Source files used for this reference
Reviewed at 7361ea0b71a5.